


LLMers Are BSing You
If you follow AI news even casually, you are constantly bombarded with headlines about how close we supposedly are to AGI, usually announced by AI CEOs competing to sound one step ahead of everyone else.
OpenAI’s Sam Altman says we are now confident we know how to build AGI. Google DeepMind’s Demis Hassabis puts it a few years out. And Anthropic’s Dario Amodei, the most aggressive of the lot, has pushed the scaling bet into outright overclaiming, arguing that powerful AI could be just one or two years away.
From Silicon Valley to Shenzhen, LLMers seem to be in a competition over who can make the wildest claim first. Bigger models will become AGI. AGI will become superintelligence. Superintelligence may wipe us out.
As a side note, the genuinely dangerous part has very little to do with some godlike machine intelligence suddenly deciding to destroy humanity, and much more to do with something far more ordinary.
Behind all this futuristic drama, though, most LLMers are making essentially the same bet: that getting from today’s AI to increasingly powerful machine intelligence, and eventually to AGI, is mainly a matter of scaling.
You know the fancy tale by now: more compute, more data, larger models, longer inference, denser GPUs and… voilà: AGI at the end of the assembly line.
There is just one problem, though…
The mathematics does not show that this assembly line leads to AGI.
Why Math Doesn’t Back Them Up
You know something is rotten in the kingdom of AI when brilliant people start waving scaling curves around as if extrapolation had suddenly become a theory of intelligence.
Sam Altman claims that model intelligence scales roughly with the logarithm of the resources used to train and run it. Well, a scaling law can tell you how the curve rises. It cannot tell you when the curve turns into a mind.
Dario Amodei’s argument is even simpler. Skip the formula, add more compute, watch LLMs acquire a broad range of cognitive capabilities, keep scaling and, somewhere up the graph, voilà: extraordinarily powerful, beyond-human systems.
At that point, the mathematics has left the room. What remains is a story about where AI might go, not a prediction of where the mathematics says it will go.
Strip away the glittering façade of GPUs, trillion-dollar infrastructure plans, benchmark curves, and promises of approaching machine intelligence, and what remains is brutally simple: the mathematics underneath does not lead to the destination they are selling, as the animation below conveniently shows.
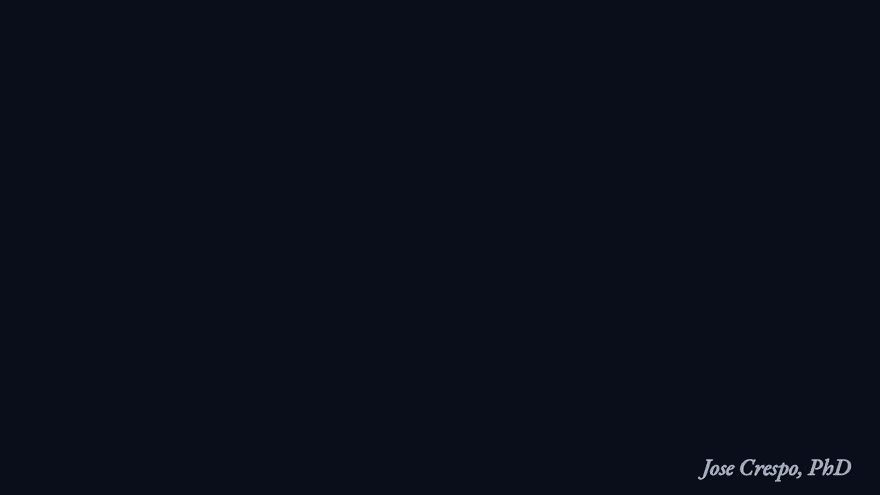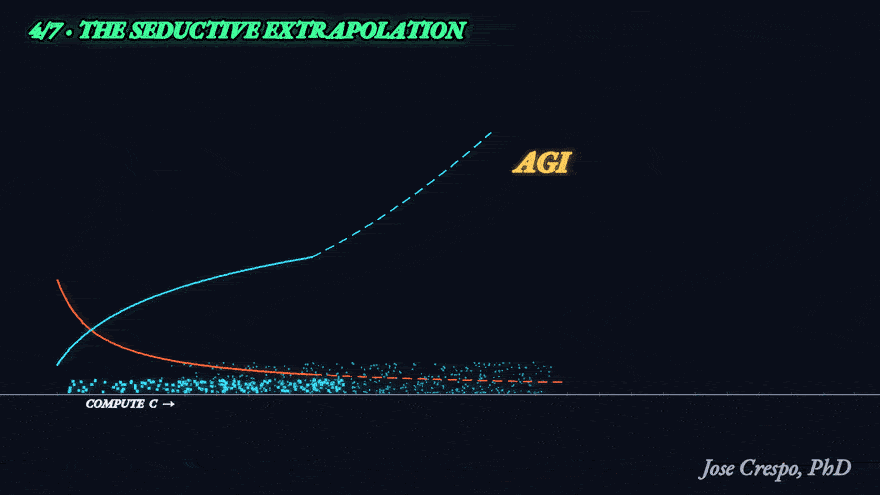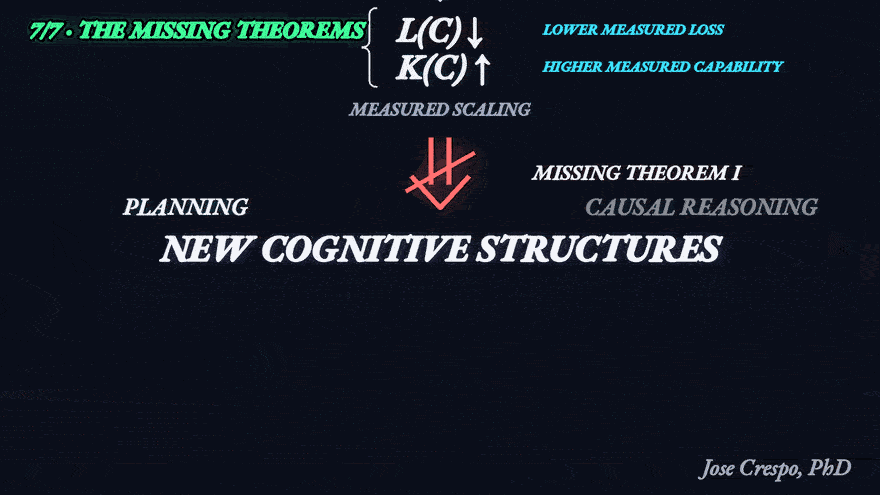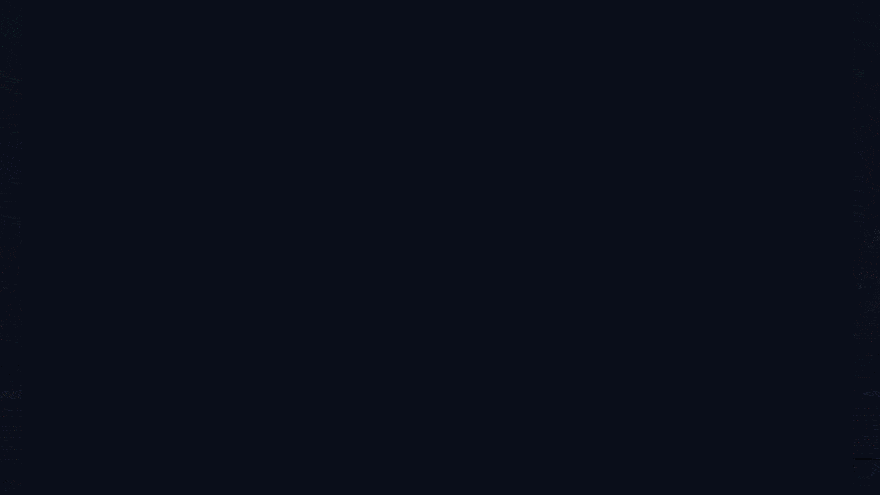
Now let’s translate the LLMers’ grand claim into plain mathematics and see what is actually hiding underneath all the LLM hype. The recipe goes something like this: take C, the computational resources we keep pouring into the machine, and…
As C grows, the measured loss L(C) falls:

Don’t panic. In plain English:

That just means: throw more compute at your AI, and the measured error goes down.
So far, no miracle. This is the boring part, and an empirically important one.
But now comes the second half of the trick.
As we keep piling on computational resources, measured cognitive capabilities can improve too. Let’s call some aggregate measure of those capabilities K(C)

Again, in plain English: More compute. More measured capability. More cognitive abilities for your AI, apparently.
Put the two together and you get the seductive little engine underneath the whole scaling dream:

And that is the basic idea: keep increasing C, and the LLM is supposed to keep moving toward AGI. Add in gains from better hardware, training, data, inference-time computation, and optimization, and you get the full package: errors go down, capabilities go up.
Repeat the recipe enough times, and you have pushed C toward the heavens, supposedly unlocking a whole new stack of mind-blowing cognitive power

And now you can see the dream of the AI CEOs in all its splendor. Run the same loop long enough, they suggest, and the machine keeps climbing: planning, abstraction, causal reasoning, persistent memory, agency, scientific discovery, general intelligence and, finally, superintelligence.
Not because anyone derived those structures from a theory of intelligence. Nobody proved they had to emerge. And the underlying architecture did not suddenly wake up one morning as a different piece of mathematics.
No. According to the LLMers, the magic ingredient is the compounding effect of scale.
Translated brutally, the proposed alchemy looks something like this
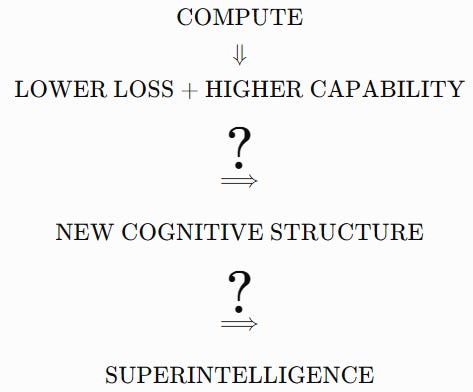
And there they are. Those two tiny question marks.
Those two question marks hide one of the biggest sleights of hand in recent technological history.
Because, as you can see in the equation below, scaling mathematics can describe the improvement on the left. What it does not give us is the missing theorem on the right:

That last transformation, from improvements in the measurable capabilities we already observe to the necessary emergence of qualitatively new cognitive machinery, is not contained in the scaling law.
That part is an extrapolation. And a massive one at that
To Build the Right Technology, Use the Right Mathematics
OK, enough beating up on the LLMers.
If throwing another mountain of GPUs at today’s mathematics is not magically going to turn an LLM into AGI, then sooner or later we have to face the annoying question:
All right, smartass. What mathematics would you use instead?
Now we’re getting somewhere. This is where the real problem begins, because the answer is not one new equation or one miraculous architecture. Nope.
We need to climb through several different mathematical worlds.
Not because mathematics is some decorative intellectual frosting you sprinkle over the engineering afterward, but because every mathematical framework determines what your machine can naturally represent, relate, transform, and reason about in the first place.
Choose the wrong abstraction and engineering can still perform miracles. It will just perform them inside the wrong mathematical universe.
So instead of asking how many more GPUs stand between us and AGI, let’s try a different question: How many mathematical revolutions might stand between us and AGI?
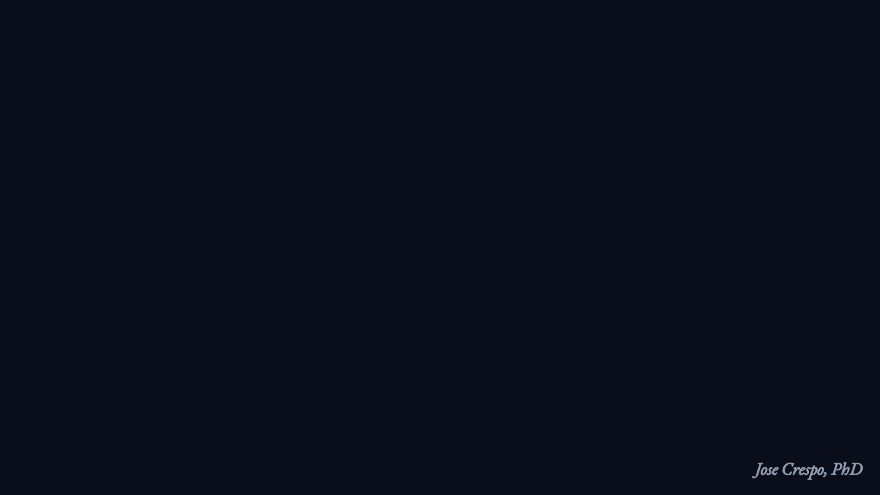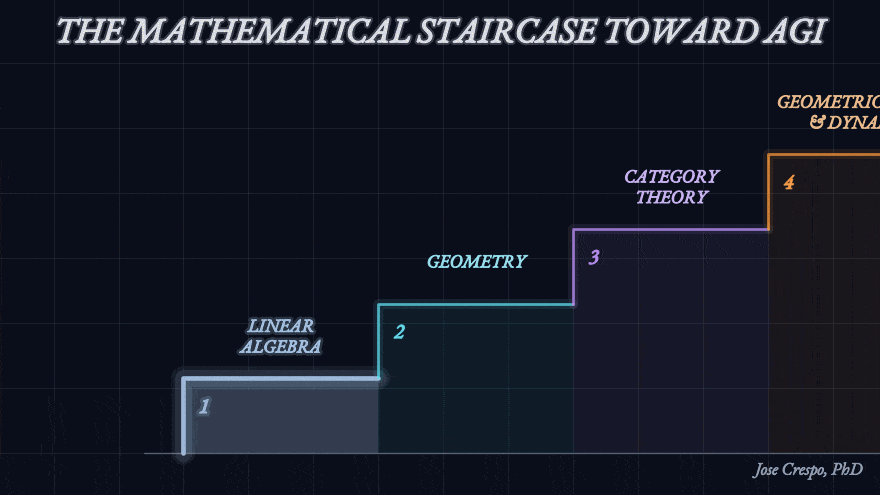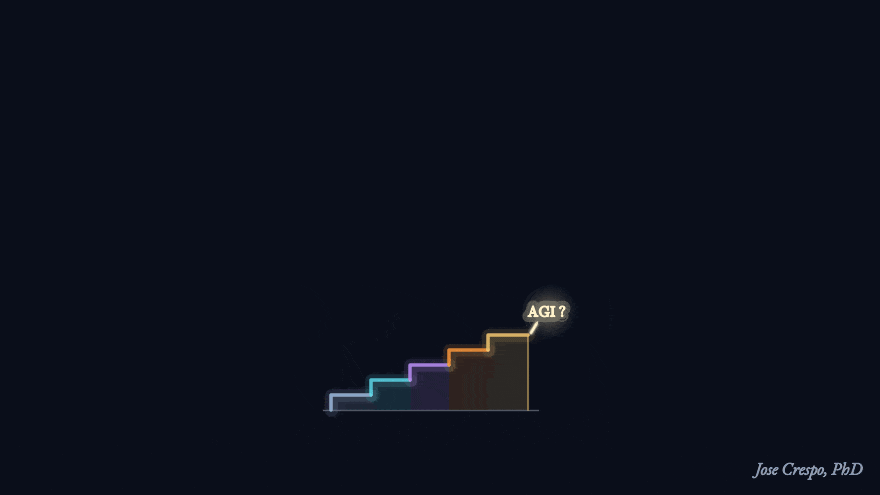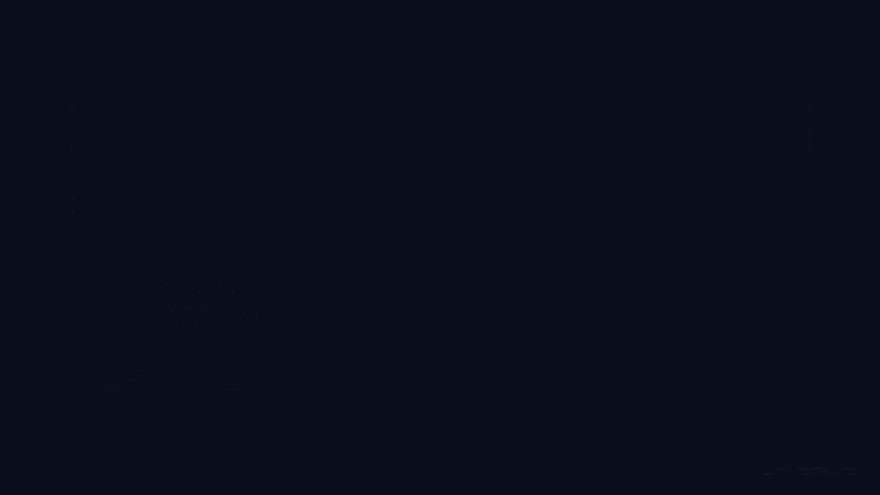
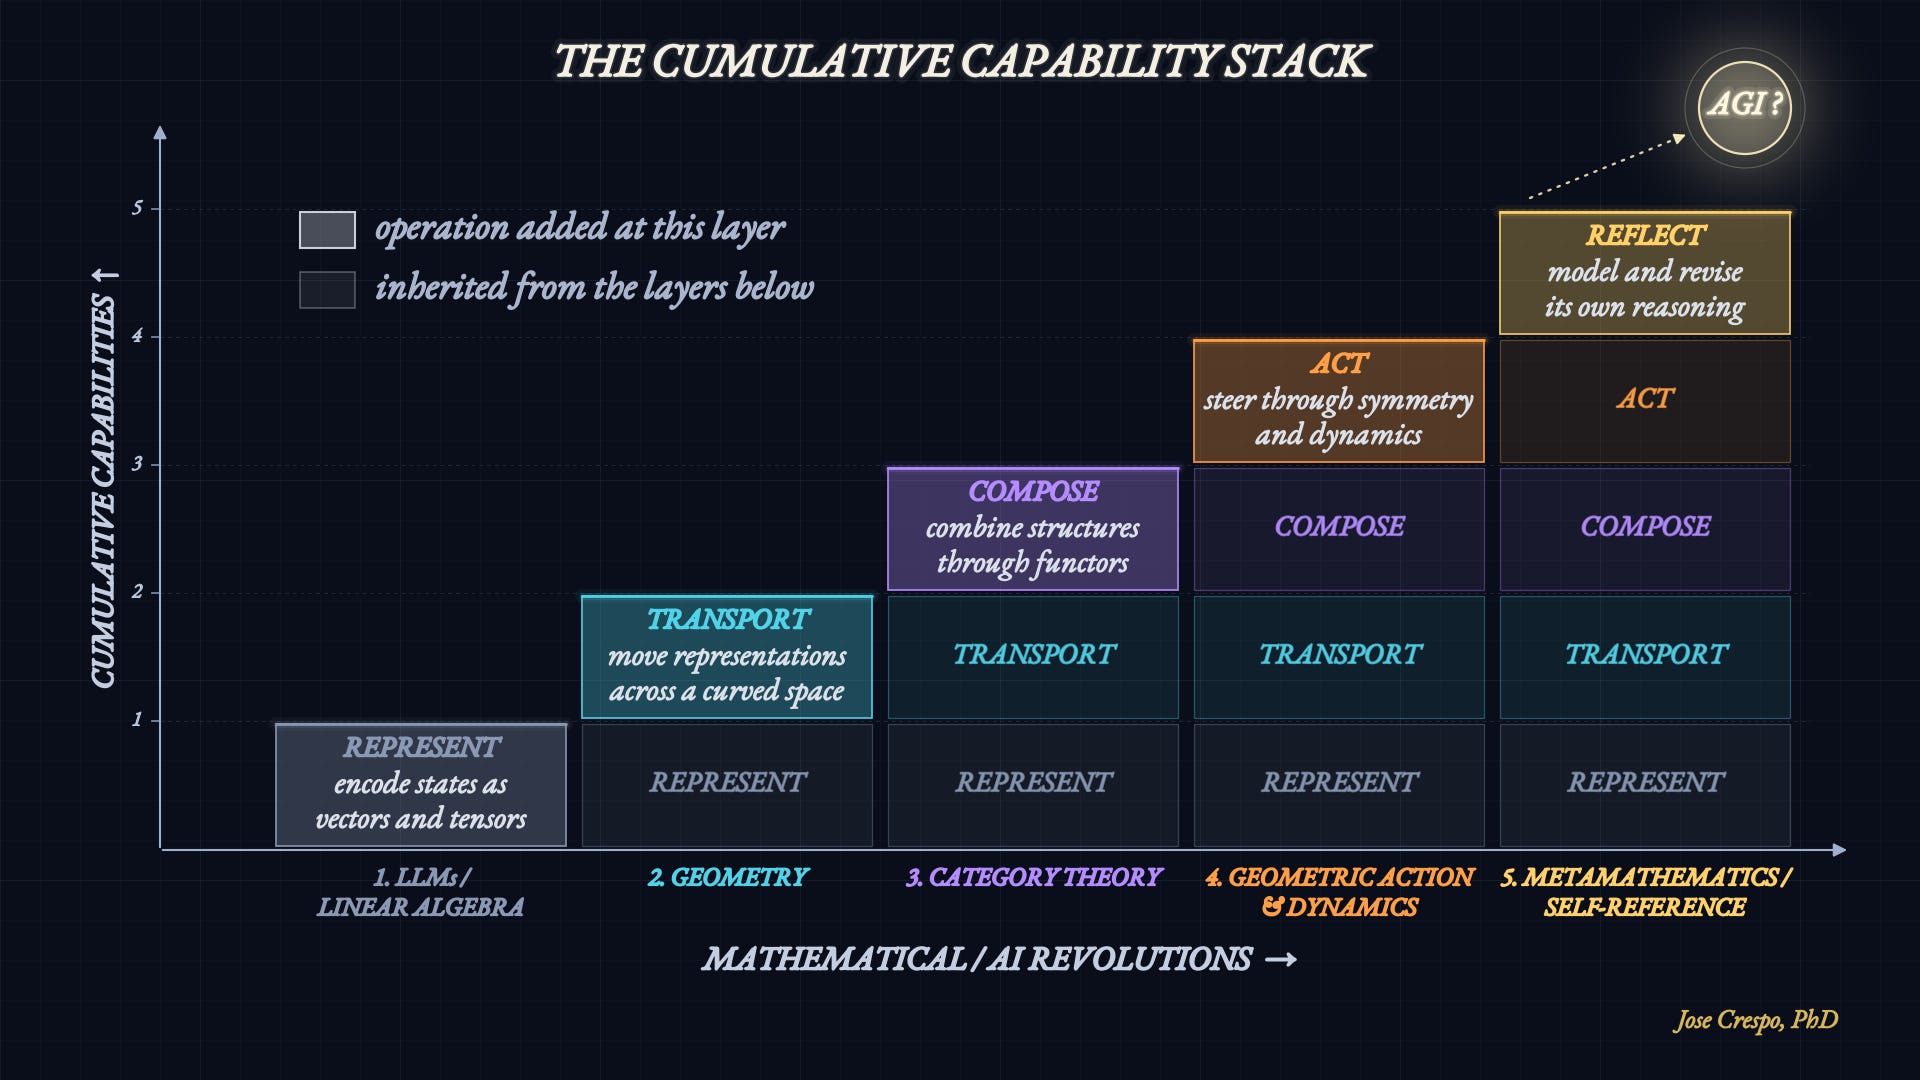
The two plots below give us a map for the climb.
The first shows the proposed cumulative capability stack: each mathematical revolution would preserve what came before while adding something fundamentally new, first represent, then transport, then compose, then act, and finally reflect.
The five steps toward AGI, summed up as an ascending ladder of verbs: Represent, Transport, Compose, Act, Reflect.
The second shows the same idea as a mathematical staircase: from today’s predominantly linear-algebraic AI, through geometry, category theory, geometric dynamics, and finally self-reference.
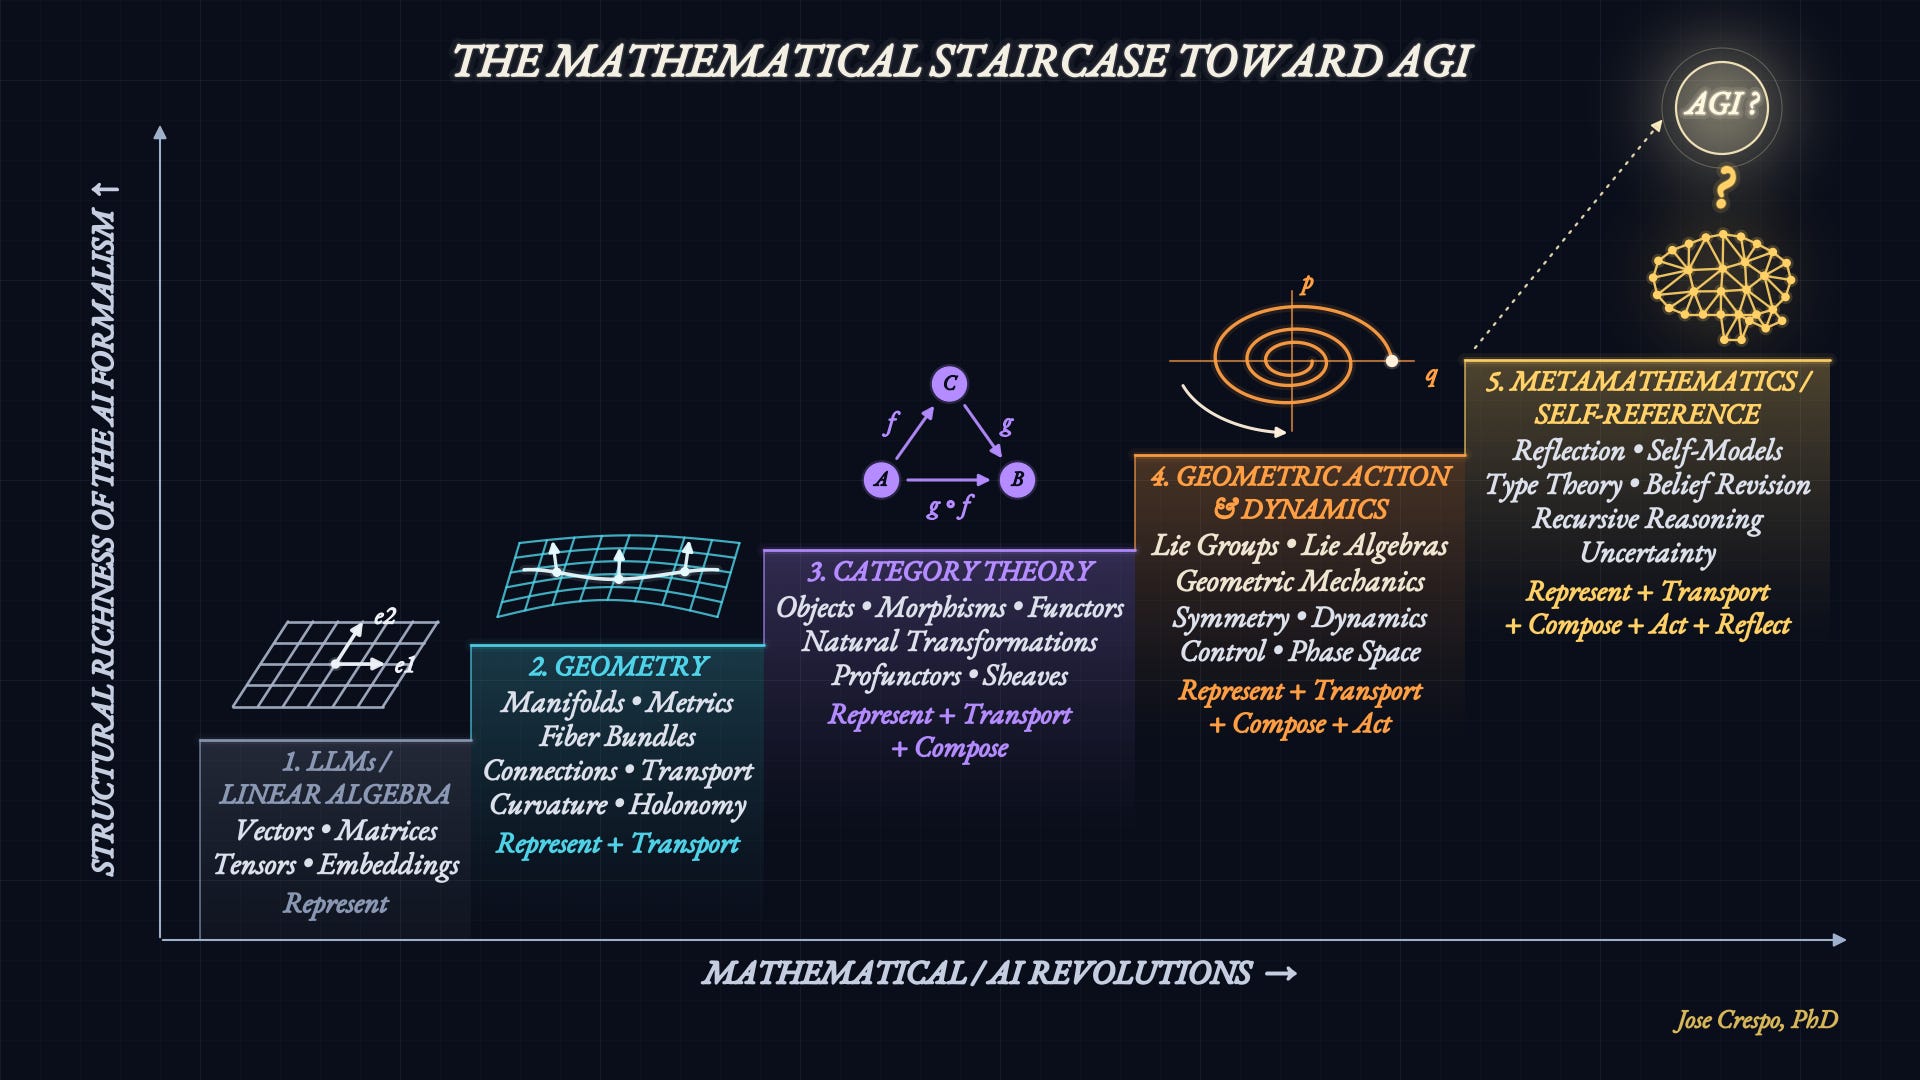
And notice the annoying little question mark sitting above the final stair.
It is there on purpose.
We should not replace the LLMers’ scaling fairy tale with our own mathematical fairy tale and pretend that five sufficiently fancy branches of mathematics automatically add up to AGI.
This is a research hypothesis based on what these mathematical frameworks might let us build, and it leaves us with a much sharper question than How big should the next model be?
We can ask instead: What mathematical structure is missing from the machine we already have?
One honest note before we climb. Researchers have already visited each of these floors on its own. Some teams add geometry to neural networks. Some use category theory, mostly to describe networks that already exist. Some build agents that act and keep a model of themselves. All real work. But each of them stays on one floor. Nobody has built a single machine that climbs the whole staircase. That is the claim of this article, and it is, as you will see, a much harder one.
So, shoes on. Buckle up.
We’re going upstairs, step by solid mathematical step, toward the final goal: a credible path to AGI.
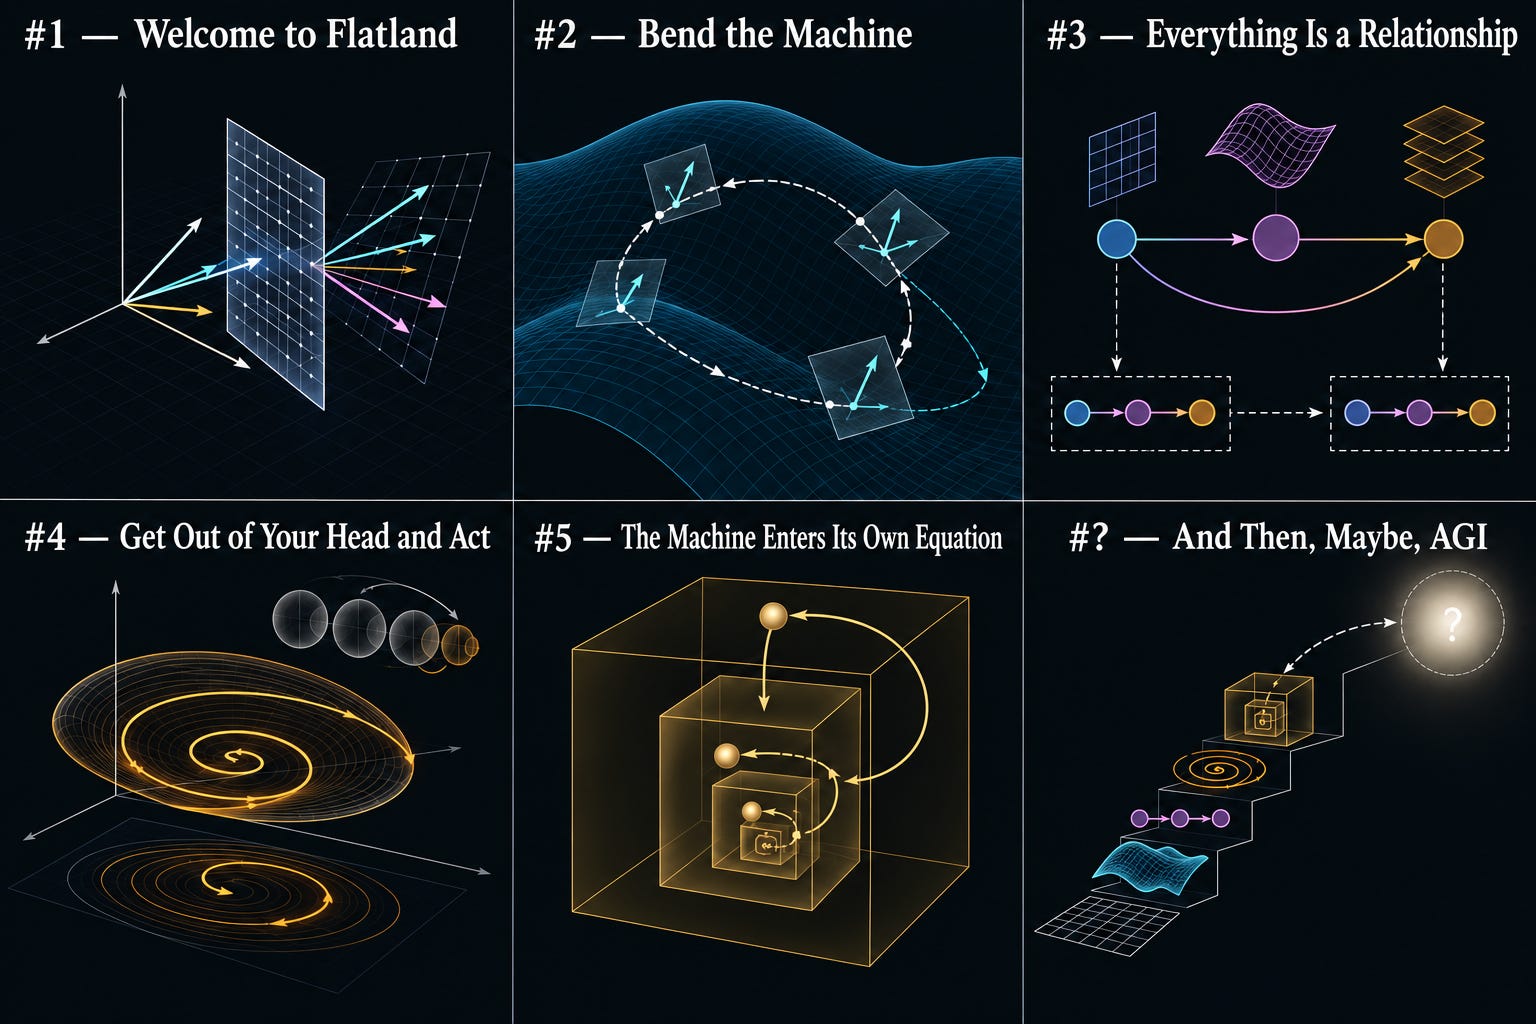
#1 — Welcome to Flatland
#2 — Bend the Machine
#3 — Everything Is a Relationship
#4 — Get Out of Your Head and Act
#5 — The Machine Enters Its Own Equation
#? — And Then, Maybe, AGI
The mathematical way upstairs to a possible AGI.
#1 — Welcome to Flatland
Today’s AI lives largely in a magnificent mathematical Flatland.
Words become vectors. Concepts become points in high-dimensional spaces. Learning becomes the transformation of those vectors through matrices, tensors and nonlinear maps.

Quick precision: the maps are nonlinear, the space isn’t. Every hidden state sits in a flat vector space with no geometry of its own. That flatness is the Flatland, not the algebra.
OK, granted: this machinery is powerful enough to explain a lot of what we see in our AI chats.
But its native language is still fundamentally one of coordinates and transformations.
That is where the geometry starts to wobble: meaning does not sit at a fixed coordinate independent of context. Its position shifts as the surrounding context changes.
The same token can mean one thing here, something subtly different one paragraph later, and something radically different when buried inside several nested contexts, references, exceptions and dependencies.
LLMs can absolutely represent context. Their hidden states and attention mechanisms do precisely that.
The deeper problem is that they do not possess an explicit intrinsic mathematical law saying: Here is how this meaning must be transported when the context changes.
So contextual consistency has to be continually reconstructed through the model’s learned transformations.
As contexts become longer, nested, conflicting or increasingly dependent on earlier distinctions, keeping the same semantic object coherent can become harder.
And eventually the machine can do something wonderfully LLM-like: Remain locally fluent while becoming globally wrong.
That is one route to what we call hallucination: not simply bad vectors, but a failure to preserve the relevant constraints and meaning across the evolving context.
Summing up, our current AI, still living in Flatland, is extraordinarily good at telling us where a representation is and how to transform it. What it does not naturally make explicit is how meaning should remain coherent as it moves through changing contexts.
Its foundational verb is:
REPRESENT.
And that missing verb gives us the reason to climb to the next floor:
TRANSPORT.
#2 — Bend the Machine
Now bend Flatland.
Instead of assuming representations merely inhabit some enormous ambient vector space, give their world intrinsic geometry: manifolds, metrics, fibers, connections, curvature and holonomy.
Suddenly the interesting question is no longer merely, Where is the state?
It becomes: How should the state change when context changes?

A connection supplies the rule for transporting information along a contextual path γ .
Curvature measures the incompatibility between different transports. Holonomy records what happens after traveling around a loop.
Now the path can matter.
That opens the door to something Flatland does not naturally make explicit: context-dependent transport and path-dependent memory.
The new verb we add at this step on our way upstairs is… TRANSPORT.
#3 — Everything Is a Relationship
Geometry gives us structured spaces. Now we step into category theory, which lets us make an even more radical move: stop treating the things themselves as the whole story.
Study how they relate and compose. Objects become connected by morphisms:

And compositions of those morphisms become mathematical objects in their own right:

Functors relate entire systems of relationships. Natural transformations relate those functorial mappings.
Sheaf-like structures can formalize how locally compatible information becomes, or fails to become, a coherent global picture. The machine is no longer merely carrying representations around.
It acquires a mathematics for asking: What can be connected to what, and what survives when those connections are composed?
Example
Imagine an AI has learned three completely different problems:
Virus → receptor → cell
Hacker → exposed service → network
Invasive species → transport route → ecosystem
To us, these look like different subjects.
Category theory gives us a language for asking whether they instantiate the same abstract pattern of relationships and composition:
OUTSIDE → GATEWAY → INSIDE
Now give the AI a problem it has never seen before.
Instead of asking only: Have I seen something similar?
it can also ask: Does this new problem have a structure I already know?
That is the potential cognitive leap: transfer knowledge by relational structure, not merely by similarity.
Current LLMs can already discover analogies like this, but often only after enormous amounts of training, and even then they may generalize them unreliably.
A category-theoretic framework could make those relationships explicit, composable, and mathematically constrained, rather than leaving them buried inside learned representations.
The machine gains a new way to reason: Don’t just recognize the pieces. Recognize how the pieces fit together… and what remains unchanged when the pieces change.
The new verb for this step is: COMPOSE.
#4 — Get Out of Your Head and Act
A sufficiently rich intelligence cannot spend eternity contemplating its representations. At some point, something has to happen.
A note for the roboticists rolling their eyes right now:
yes, you’ve had rigid-body groups and geometric control since the 1980s. True. But that math lives in the controller, bolted on under a perception model that still thinks in Flatland. The step isn’t inventing the tools. It IS moving them into the reasoning core, so the machine’s representations flow on the same geometry its body obeys.
That probably sounds like mathematical soup, so let’s give it arms and legs.
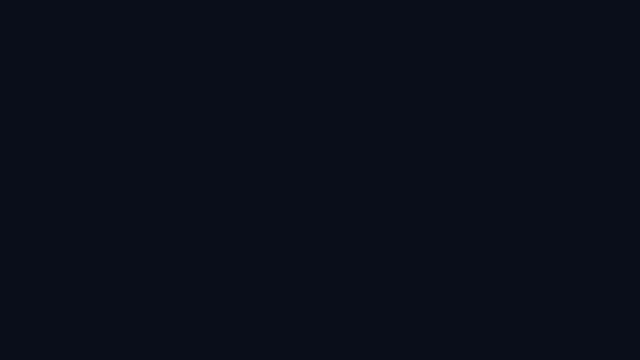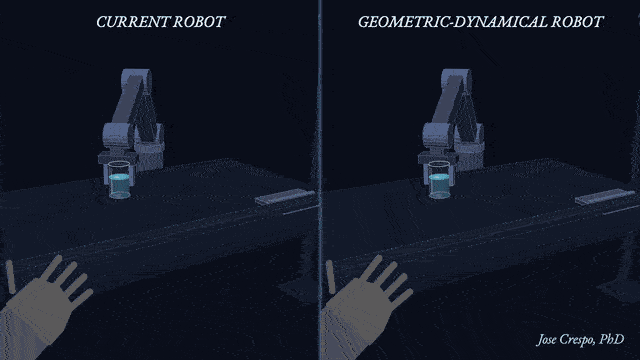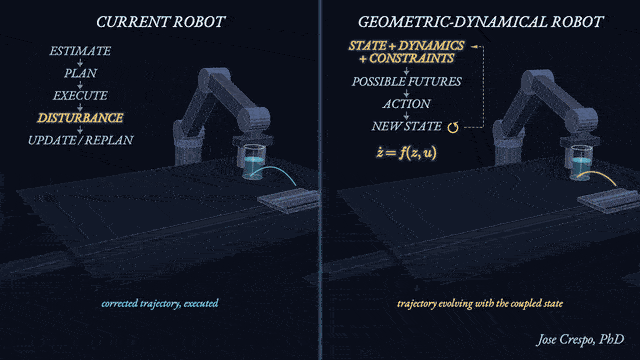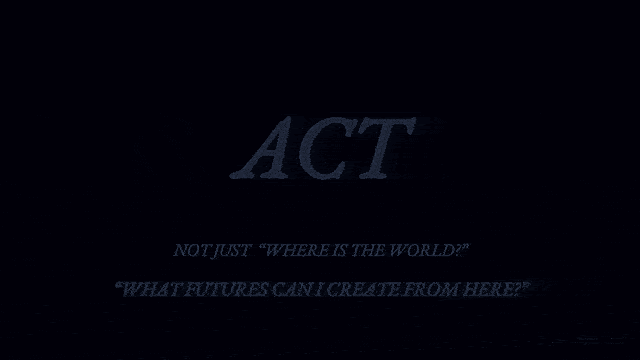
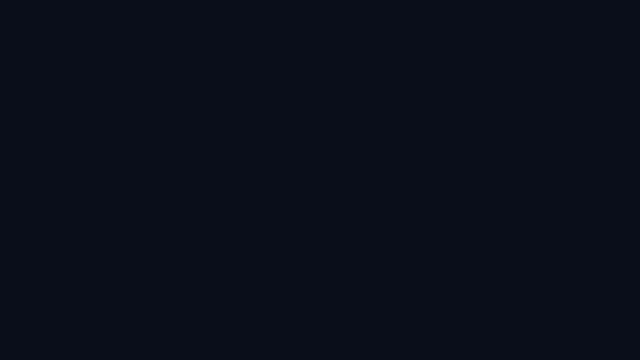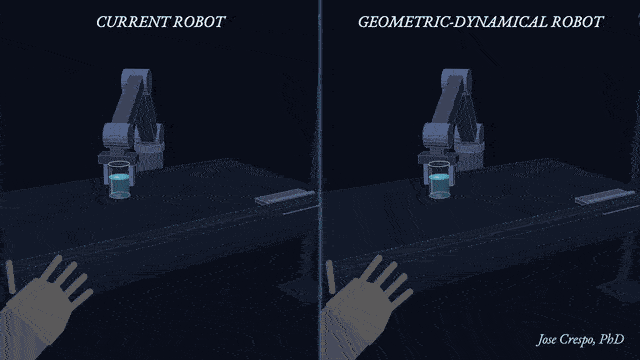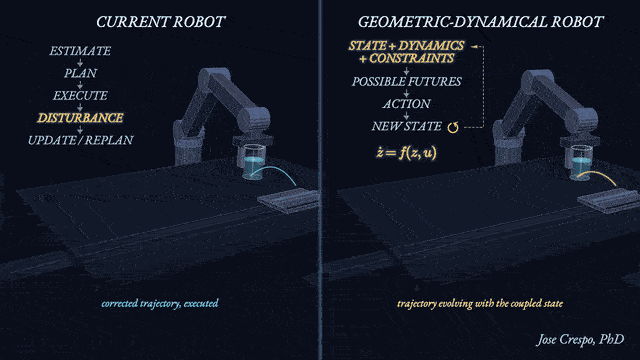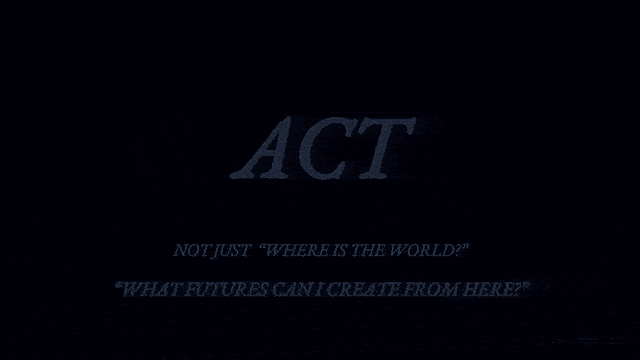
Imagine two robots standing in a kitchen (see the animation above). You tell both: Grab that glass without spilling the water and put it on the moving tray.
A current-generation robot might perceive the glass, estimate its coordinates, calculate a grasp, generate a trajectory for its joints, execute it, measure the error, correct, and repeat.
Very impressive. But now somebody bumps the table…
The glass begins sliding.
The water starts oscillating.
The tray keeps moving.
The robot’s shoulder approaches its mechanical limit. Its fingers are already applying force to the glass.
And all of these things are changing at the same time.
Now the problem is no longer:
Where is the glass?
It is:
What actions can I physically perform from this exact state, while the world itself is evolving, without violating the constraints of my body, the glass, the water, and the task?
That is a radically more geometric question.
The robot’s orientation is naturally described by rotations such as:

while its position and orientation together can be represented through rigid-body transformations such as:

The small moves it can make right now, from that exact pose, form what mathematicians call the Lie algebra: the list of nudges currently available to the robot. And the robot is not alone in this dance:
Its body has velocities and momenta.
The glass has its own dynamics.
The moving tray has another trajectory.
The sloshing water introduces still more dynamical constraints.
The state therefore does not merely sit somewhere waiting for the next command. It flows.

And every action changes which futures remain physically possible.
A geometrically richer robot could reason directly over this evolving structure: continuously transform its frame of reference, predict families of possible trajectories, exploit symmetries, respect physical constraints, and continuously adapt its actions as the world changes.
The table gets bumped? It does not simply say: Oops. Recalculate coordinates.
It asks something closer to: Given the new state of this entire coupled system, which physically admissible trajectory still gets the glass onto that tray without spilling the water?
That is the conceptual jump.
Not: SEE → CALCULATE → MOVE
But:
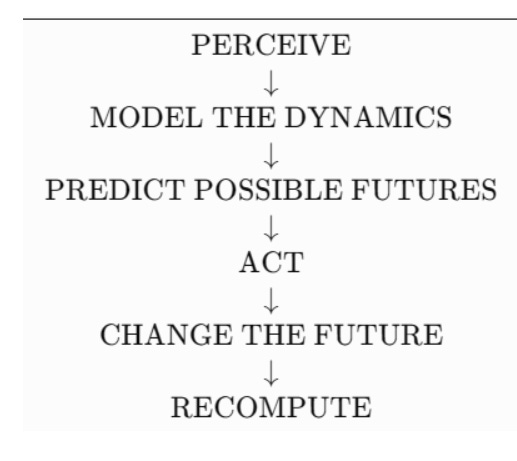
There you go. The new verb: ACT.
#5 — The Machine Enters Its Own Equation
So far, the machine has been modeling something else: language, contexts, relationships, worlds, actions.
But an intelligent system is itself part of the world it is trying to understand.
So eventually the arrow turns around:

The system begins representing aspects of itself: its beliefs, uncertainty, previous reasoning, actions, limitations, and perhaps even models of its own models.
Now we enter the territory of reflection, self-reference, recursive structures, type theory, belief revision and metamathematics.
This does not mean the machine suddenly becomes conscious.
Mathematics gives us no such free miracle.
The more defensible claim is stranger and more precise: The reasoner becomes one of the objects being reasoned about.
One warning comes with this floor. Mathematics proved long ago that no system can fully check its own reasoning from the inside (Gödel and Löb). A machine that thinks about itself inherits that limit. So the goal is not a machine that knows itself completely; that door is locked. The goal is a machine that knows how sure it is, can change its mind about itself, and knows where its self-knowledge ends. That much is within reach
The new verb is: REFLECT.
SUMMING UP: LLMs Are Step Zero
LLMs are not the end of the road to intelligence. They are step zero. And the good news is that we are not mathematically empty-handed.
Geometry, category theory, dynamics and self-reference already give us candidate tools for building machines that can do more than represent: transport, compose, act, and reflect.
Will that get us to AGI? We don’t know.
That question mark is still there.
But at least now we have something more interesting to investigate than how many GPUs we can pile onto Flatland.
The next revolution in AI will begin when we stop asking how much bigger we can make today’s machine and start asking what mathematics tomorrow’s machine is still missing.
Don’t just scale Flatland. Get out of it. The next revolution is upstairs.